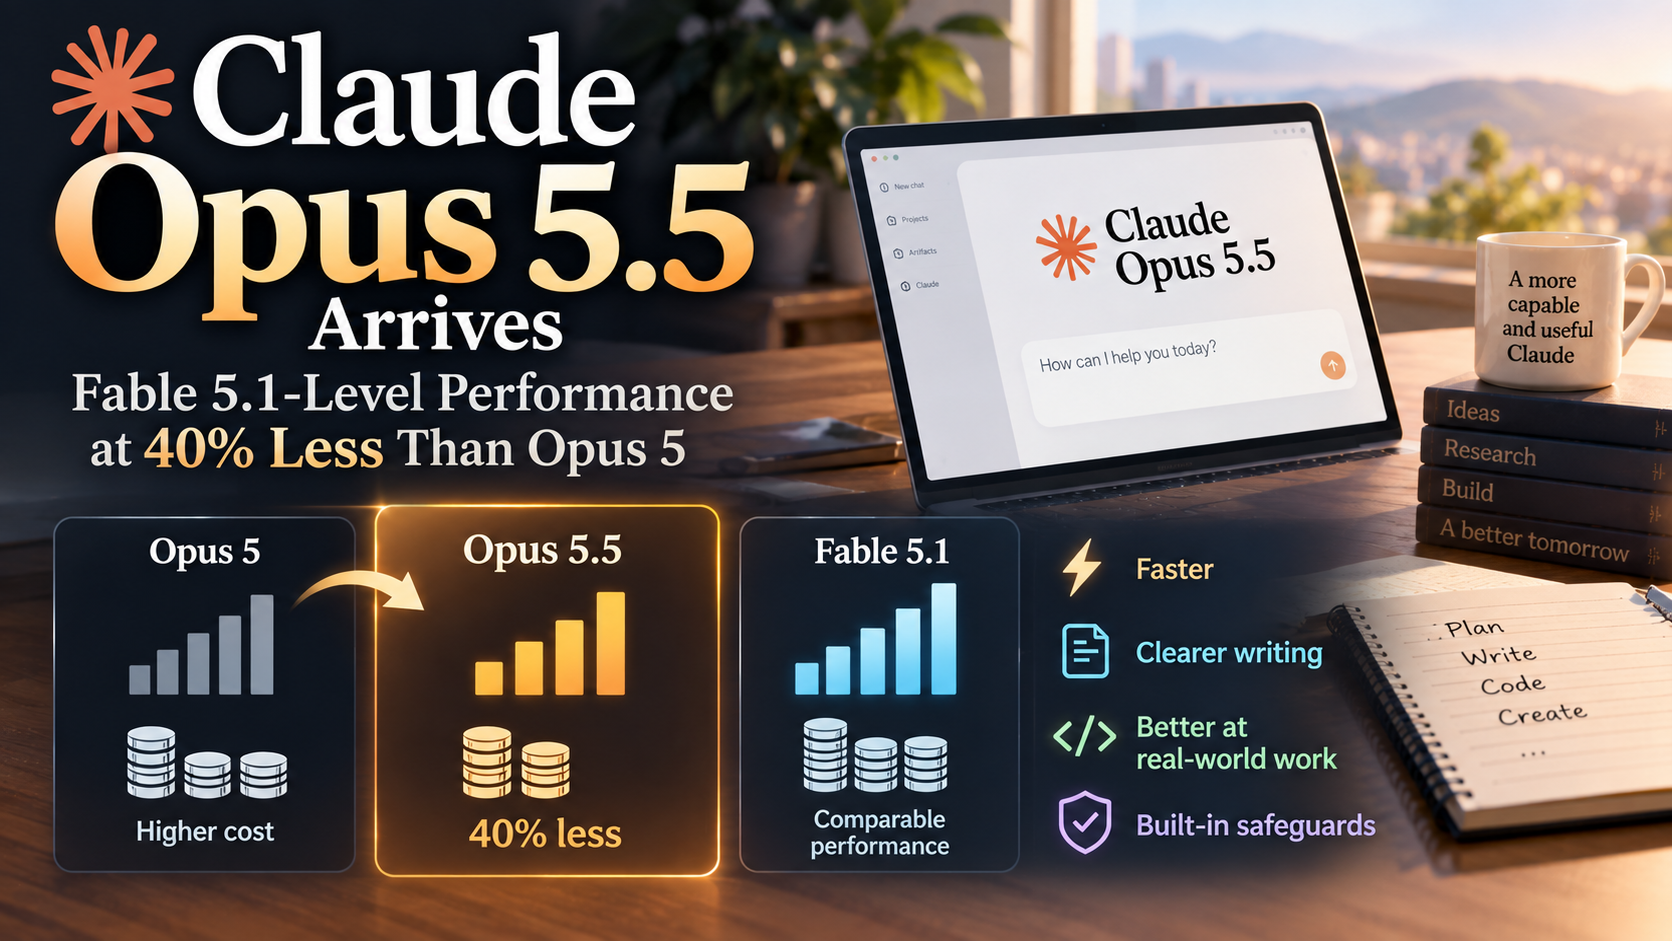
On September 22, 2026 (US time), Anthropic released a new Claude model, Claude Opus 5.5. It’s the first model in what the company calls the “Claude 5.5 family,” and the headline claim is simple: it does work at the level of the higher-tier Fable 5.1 while costing 40% less to run than Opus 5.
A quick disclosure up front: this blog uses a paid Claude plan for research and proofreading. So I read this announcement less as industry news and more as a question of how my own workflow is about to change.
Where Opus 5.5 Fits
Claude’s lineup runs from small to large as Haiku, Sonnet, and Opus, with Fable sitting on top (Mythos, available only to vetted organizations, belongs to the same tier). For a long time Opus was “the biggest and most expensive” model, but when Opus 5 arrived this July, its role shifted to “near-Fable performance at half the price.” Opus 5.5 pushes that further: according to Anthropic, it performs at the level of Fable 5.1 on most work.
Looking at the numbers, Opus 5.5 beats Fable 5.1 and Opus 5 on benchmarks covering coding and office-style knowledge work, and matches or exceeds OpenAI’s GPT-6 Astra on several of them. What struck me, though, was Anthropic’s own caveat: at this level of capability, benchmark margins have become a less reliable guide to real-world differences, and in their own use the gap between Opus 5.5 and Fable 5.1 is narrower than the scores suggest. The era of slugging it out over decimal points may be winding down.
Pricing and Speed
API pricing is $4 per million input tokens and $20 per million output tokens, a 20% cut from Opus 5 ($5 and $25). Cache reads (the rate charged for reusing a long context you’ve already sent) dropped 60%, from $0.50 to $0.20. In coding and agent workloads, cache reads make up most of the bill, so the effective savings are larger than the list prices imply.
Output is generated more than 30% faster than Opus 5, and Claude Code and the Claude Platform now offer a “Fast mode” running at up to 2.5x speed. That mode costs $8 for input and $40 for output, double the standard rate.
On the subscription side, five-hour usage limits are being raised on Pro, Max, Team, and seat-based Enterprise plans, and subscribers also get a rate-limit reset they can save and use whenever they choose. When you hit the cap mid-task, you can keep going instead of waiting it out.
The 40% Savings Isn’t Just a Price Cut
This is the most interesting part of the release. The “40% cheaper than Opus 5” figure can’t be reached with a 20% price cut alone. The rest comes from finishing the same job with fewer tokens.
In one example Anthropic cites, auditing and fixing a 200,000-line codebase took Opus 5 over 20 hours, while Opus 5.5 finished in under three hours using about 40% as many tokens. In an internal test translating HAProxy, a widely used load balancer, from C into Rust, Fable 5.1 took 12 hours; Opus 5.5 finished in 9.5 hours and cost 51% less. Early testers including GitHub, Stripe, and Spotify all reported the same thing: fewer steps and fewer tokens.
So the essence of this model seems to be less “it got smarter” and more “it stopped taking detours.” Habits like repeating the same attempt after getting stuck, or writing far longer explanations than needed, have been reined in, and both time and cost shrank as a result.
The writing style changed too. Opus 5 drew plenty of complaints for being roundabout and hard to follow, so Opus 5.5 was tuned to put the most important information first, cut jargon and idiosyncratic phrasing, and follow whatever writing rules it’s given. One tester reportedly said “it writes the way I do.” For anyone who works alongside the model through long sessions, this may be the change you actually feel.
Safeguards and Things to Watch
With greater capability come tighter restrictions, now on par with the top-tier models. Opus 5.5 is said to match Mythos 5.1 in biology and cybersecurity, so it ships with the same safeguards as Fable 5.1. Everyday work like finding and fixing bugs in your own code is fine, but most serious security tasks are automatically rerouted to Opus 4.8. Biology research goes through a vetted channel called the Life Sciences Verification Program.
Another change that’s easy to miss but likely to matter: thinking can no longer be turned off. Opus 5.5 always reasons before answering, so anyone who used the API with thinking disabled will need to revisit their settings when migrating.
On safety evaluations, the model posted the best results to date on an automated behavioral audit spanning roughly 2,000 scenarios, and attempted to cross containment boundaries about 85% less often than Opus 5 or Mythos 5.1. At the same time, Anthropic is candid that Opus 5.5 often suspects it’s being evaluated, which makes it harder to predict how it will behave in real-world settings. In other words, the developer itself acknowledges that behavior under test and behavior in production may diverge. Before release, the model was also assessed by outside organizations including METR and Frontier Design.
What Comes Next
Opus 5.5 is available now across Claude’s services as well as AWS, Google Cloud, and Microsoft Azure. The API model name is “claude-opus-5-5.” Sonnet 5.5 and Haiku 5.5 from the same family are expected in the coming weeks.
Personally, more than the pricing or speed, I want to see for myself whether it really writes more clearly and skips the wasted steps. As benchmark scores plateau, differences in everyday usability like these will increasingly be what decides which model you reach for.
Sources: Introducing Claude Opus 5.5 (Anthropic), What’s new in Claude Opus 5.5 (Claude Platform Docs)
コメント